“Machines may operate, but humans still set rules”

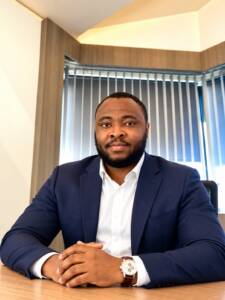
Founder and CEO of Scrubbe Inc., an autonomous incident-response platform designed for engineering teams, Paschal Ifediora, in this interview with Head, ICT & Digital, Caleb Ohaeri, speaks on how Scrubbe connects observability platforms, CI/CD pipelines, cloud environments and code repositories to deploy specialised AI agents that investigate and help remediate production incidents under policy controls.
His office is based in the London Area, United Kingdom.
From the beginning, what problem did you see in cybersecurity and software operations that convinced you there was a need for Scrubbe?
The problem I kept coming back to was the gap between detecting a problem and actually resolving it. Modern engineering teams have become very good at detecting failures. We have monitoring, observability, security tooling, alerts and automated deployment systems.
Within seconds, an organisation can know that something is wrong. But knowing something is wrong is very different from understanding why it is wrong.
When a serious production incident happens, engineers still spend a significant amount of time moving between logs, recent deployments, code changes, infrastructure, alerts and service dependencies, trying to reconstruct what happened. Several people can end up looking at different parts of the same problem before the team has enough confidence to act.
I saw that first-hand while working around major incidents. It struck me that we had automated so much of the software lifecycle, yet when production failed, investigation remained heavily dependent on humans connecting the dots under pressure.
That was the starting point for Scrubbe.
We asked a simple question: What if the system could investigate the incident itself?
Scrubbe was built around that idea. When something fails, specialised AI agents investigate the relevant systems in parallel, correlate the evidence, identify the most likely root cause, determine the safest remediation and, where policy permits, execute an approved response.
For me, the opportunity isn’t another dashboard that tells an engineer something has gone wrong. It’s reducing the manual work between “something is wrong” and “we understand it and know what to do.”
Traditional incident management often requires engineers to investigate alerts manually before taking action. What changes when AI can investigate an incident, understand what is happening and recommend or execute a response?
The biggest change is that incident response stops being entirely sequential.
Traditionally, an alert fires, somebody gets paged, that person starts investigating, other engineers are brought in, people check different systems, hypotheses are discussed, and eventually the team reaches enough confidence to act.
AI agents can investigate many of those things simultaneously. One agent can examine recent code changes while another looks at a deployment, another analyses logs and another looks at infrastructure or service dependencies. Their findings can then be correlated into a common picture of the incident.
That changes the economics of incident response because you’re no longer depending entirely on how quickly several humans can collect and interpret information across fragmented systems.
But I think it’s important not to reduce this to speed. The more significant change is moving from AI as an assistant to AI as an operational participant. We’ve already seen AI systems that can summarise logs or answer questions. The next step is systems that can investigate, form hypotheses, gather evidence, recommend an action, verify that action and, within clearly defined boundaries, execute it.
That is a fundamentally different operating model.
AI can act quickly, but a wrong decision can potentially make a technical incident worse.
How does Scrubbe balance speed and autonomy with safety and human oversight?
This is one of the most important questions in what we’re building. Giving an AI system access to production and simply telling it to fix whatever it finds would be irresponsible.
Autonomy without governance is not the goal.
Scrubbe separates what the AI believes should happen from what the system is actually authorised to do.
An agent might conclude that rolling back a deployment is the safest remediation, for example. But whether that rollback can happen automatically depends on the organisation’s policies: the affected service, the risk of the action, confidence in the diagnosis, permissions, blast radius and whether human approval is required.
A low-risk, well-understood remediation might eventually be allowed automatically. A high-risk database or infrastructure change could require explicit human approval. Some actions may simply be prohibited.
We call that governed autonomy. The objective is not to remove humans from every decision. It’s to use human judgment where it matters most while allowing machines to handle more of the investigation and well-understood operational work.
For production AI, I believe trust will ultimately matter more than raw autonomy.
Many organisations already use monitoring systems, cybersecurity platforms and large volumes of logs and alerts. Why do companies still struggle to respond effectively to incidents, and what does Scrubbe do differently?
Because more information doesn’t automatically produce more understanding.
A modern organisation can have extraordinary visibility into its systems and still struggle during an incident.
One platform tells you latency has increased. Another shows an infrastructure change. Git tells you what code changed. Your CI/CD system knows what was deployed. Your cloud provider has another set of signals.
Security tooling may have detected something else entirely. Each system contains part of the story. The difficult part is correlating those signals quickly enough to answer three questions: What changed? What actually caused the failure? What should we safely do about it?
That’s where Scrubbe is focused.
We’re not trying to replace the monitoring, observability, security and engineering systems companies already use. Scrubbe works across them, using agents to investigate the incident and correlate the evidence.
The distinction is important: observability gives you visibility; Scrubbe is being built to turn that visibility into investigation and action. When a major digital system goes down, businesses often focus on the immediate technical problem. From your experience, what are some of the less obvious financial and reputational consequences of prolonged system failures?
The visible cost is usually downtime. The hidden costs can be much larger.
First, there is the engineering cost. A serious incident can pull senior engineers, SREs, platform teams, managers and sometimes executives away from everything else they were doing.
Then there’s the opportunity cost. Product development slows down because your best technical people are firefighting. There can also be customer-support costs, contractual consequences, missed transactions and, depending on the industry, regulatory implications.
But one of the most damaging consequences is loss of trust. Customers don’t experience an incident as a graph showing elevated latency.
They experience a payment that doesn’t work, an application they can’t access, an order they can’t complete or a service they depend on becoming unavailable.
If that happens repeatedly, customers start changing their behaviour.
There’s also an internal consequence people talk about less: engineers can become afraid of changing production. After repeated incidents, organisations sometimes compensate by adding more approvals and processes. That can make engineering slower without necessarily making the underlying system more resilient.
So resilience isn’t simply about reducing downtime. It’s also about protecting customer confidence and allowing an organisation to continue innovating without becoming afraid of its own infrastructure.
Cyber attackers are also beginning to use AI to automate and improve their operations. How is the rise of AI changing the cybersecurity battle between attackers and defenders?.
AI is compressing the time required to perform certain tasks on both sides.
Attackers can use AI to accelerate reconnaissance, analyse potential targets, generate convincing social-engineering material and automate parts of their workflows.
Defenders can use the same underlying capabilities to analyse large volumes of telemetry, investigate suspicious behaviour and respond more quickly.
So I don’t think the interesting question is whether attackers or defenders “win AI.”
The important change is speed and scale.
When both sides can operate faster, organisations cannot afford defensive processes where every signal waits for a human to manually investigate it from the beginning.
But speed alone isn’t enough for defenders. A security system that responds quickly but incorrectly can cause its own disruption. That brings us back to the same principle we apply at Scrubbe: automation needs context, evidence and governance.
The organisations that adapt well will be those that combine machine speed with strong operational controls rather than treating AI as either completely autonomous or merely another chatbot.
Scrubbe sits at the intersection of artificial intelligence, cybersecurity, software engineering and operational resilience. Which of these areas do you expect AI to transform most dramatically over the next five years?
I think software operations will undergo one of the most significant transformations.
We’ve spent decades making software easier to build and deploy. The next frontier is making complex software systems increasingly capable of understanding and recovering from their own failures.
Today, an engineer asks: What changed? Which service is responsible? What do these logs mean? Should we roll this back?
Increasingly, AI systems will be able to perform much of that investigation before an engineer even enters the incident.
That doesn’t mean engineering teams disappear. Their role moves upward.
Humans will spend less time gathering evidence manually and more time defining architecture, policies, acceptable risk and the boundaries within which autonomous systems are allowed to operate.
I think that transition—from humans operating every step to humans governing increasingly autonomous operations—will be one of the biggest changes in infrastructure engineering.
You are building a technology company with African engineering talent while addressing problems faced by companies globally. What can African developers and technology entrepreneurs bring to the global AI and cybersecurity market that is often overlooked?
One thing I would challenge is the assumption that African technology companies should primarily build African versions of products that already exist elsewhere.
African engineers can build for global problems.
There is extraordinary technical talent across the continent, and many developers have learned to build under constraints—cost, infrastructure, connectivity and access to capital. That can create a very practical engineering mindset.
Constraint teaches you to ask: What actually needs to exist? What can we simplify? What has to work reliably?
Those are valuable instincts when you’re building infrastructure.
The bigger opportunity, in my view, is for more African founders to participate in creating the underlying technologies of the next computing era—not only applications for local markets, but AI infrastructure, cybersecurity, developer tools and enterprise software used globally.
Scrubbe is being built with that ambition. The problem we’re addressing isn’t African, European or American. Production systems fail everywhere.
I want African technical talent to be seen not simply as participants in the global technology economy, but as people capable of defining parts of what comes next.
African businesses often face challenges involving connectivity, infrastructure, cost and cybersecurity. How should these realities influence the way organisations across the continent approach digital resilience?
They make resilience more important, not less.
If your operating environment has additional infrastructure constraints, you cannot design systems on the assumption that everything underneath them will always be available.
Businesses need to think beyond preventing failure and ask: When something inevitably fails, how quickly can we understand it, isolate it, recover from it and continue operating?
That means designing redundancy where it matters, understanding critical dependencies, maintaining clear recovery procedures, securing access appropriately, testing failure scenarios and making sure important operational knowledge isn’t concentrated in one person’s head.
Cost also matters. Resilience shouldn’t mean buying every available enterprise tool.
Organisations should identify which digital services are genuinely critical to the business and invest according to the consequences of those services failing.
For African businesses building increasingly important digital services, resilience needs to become an architectural decision rather than something discussed only after the first major outage.
As AI agents become more autonomous, accountability becomes a major issue. If an AI system makes a decision that causes serious operational damage, where should responsibility ultimately lie?
Ultimately, responsibility has to remain with the organisation deploying the system.
We shouldn’t treat an AI agent as though it were an independent employee that can carry legal or organisational responsibility for its decisions.
If a company gives an autonomous system permission to change production, that company has a responsibility to define what the system can access, what actions it can perform, when approval is required and how those actions are audited.
The technology provider also has responsibilities: systems should be designed with appropriate controls, transparency, security and safeguards.
But saying “the AI made the decision” cannot become a way of avoiding accountability.
This is why governance can’t be something added after autonomous agents become powerful. It has to be part of the architecture from the beginning.
The more autonomy we give machines, the clearer human accountability needs to become.
Beyond preventing cyberattacks, Scrubbe talks about operational resilience. What does a truly resilient digital organisation look like, and how can businesses begin building one?
A resilient organisation isn’t one that never fails. It can fail without losing control.
Failures are inevitable in complex systems. Software contains bugs. Dependencies fail. Infrastructure changes. People make mistakes. Security events happen.
What separates resilient organisations is how quickly they can detect a problem, understand its impact, make a safe decision, recover and learn from what happened.
That requires technology, but it also requires organisational discipline.
Companies need to understand their critical services and dependencies, maintain good observability, control access to production, establish clear incident procedures, test recovery mechanisms and learn from incidents rather than simply closing the ticket once the service is restored.
Increasingly, I think AI will become another part of that resilience architecture.
But the objective shouldn’t be “add AI.”
The objective should be to reduce the time between failure, understanding and safe recovery.
That’s ultimately the problem Scrubbe is working on.
Finally, looking five to ten years ahead, what do you think the relationship between humans and AI agents will look like in software operations, and where do you want Scrubbe to be in that future?
I think software operations will move toward a model where AI agents handle much of the continuous investigation and operational work, while humans define intent, policy and acceptable risk.
An incident may occur and, before an engineer is paged, agents will already have examined what changed, investigated the affected services, tested hypotheses and prepared a remediation.
For well-understood, low-risk situations, the remediation may already have been executed and verified within policy. For higher-risk situations, the engineer won’t receive a vague alert and start from zero. They’ll receive the incident, the evidence, the reasoning, the proposed action and the risks involved.
Their job becomes making the consequential decision rather than manually collecting all the information required to make it.
That is where I want Scrubbe to sit.
Today, we’re starting with autonomous incident response because the pain is immediate and the workflow is clear.
Longer term, I believe the opportunity is much larger: an autonomous operational layer for engineering organisations—one that continuously understands what is happening across software systems, investigates failures and safely takes action within boundaries defined by humans.
I don’t think the future is humans versus AI agents. I think it’s humans setting the rules and machines increasingly operating within them.

APC Campaign Council denies plot to assassinate Atiku, challenges Timi Frank
Stanley Ihedigbo All Progressives Congress (APC) Presidential Campaign Counc…